Hamiltonian Research

Language models that write the whole answer at once.

Most models write one word at a time. Ours starts from blanks and fills in the words it is surest of, pass after pass, on a state-space backbone instead of attention.

An independent research lab in Abu Dhabi.

Why is the sky blue?

The answer starts as thirty-two blanks.

Pass 0 of 8

Illustrative. Words stand in for tokens. The bar under each is the model's confidence when it committed.

A different machine for language.

DIMBA pairs masked diffusion with a bidirectional Mamba-2 backbone. It reads the whole masked sequence from both directions, commits the tokens it is most sure of, and repeats until no masks remain.

Every other masked diffusion text model we know of sits on a transformer.

Constant memory

A fixed-size state per layer. Long context costs linear time, and nothing piles up in a cache.

Whole-answer refinement

Many positions fill in parallel. The model can reconstruct missing text and resists repetitive loops.

A dial, not a size

The number of passes is a setting. More compute for a better answer, less for a faster one, same weights.

Honest numbers from the first public model.

hr-diffuse-1-nano, a 288M-parameter DIMBA model distilled from SmolLM-135M, lost the factual test to its teacher and led every baseline on infill. The losses are published with the wins.

Model Factual answers40 questions, higher is better Repetitive loopslower is better Infill recoveryhigher is better
hr-diffuse-1-nano15.0%7.5%14.0%
SmolLM-135M, the teacher82.5%37.5%2.9%
SmolLM-135M-Instruct60.0%2.5%0.0%
GPT-220.0%90.0%0.0%
Pythia-160M10.0%15.0%1.7%

From the July 2026 technical report. SmolLM-135M-Instruct loops less than nano, so no general claim about repetition.

6

self-correction methods tried. None worked at this scale.

52.5%

critic precision at flagging a wrong token. Chance is 10%.

78.9%

of real errors ranked above a correct token. Chance is 50%.

Writing

Technical reportFaris Allafi, July 2026

I trained a language model that thinks the capital of Japan is Paris

What the first model gets right, what it gets wrong, and what we would do with more compute.

Read the report or download the model on Hugging Face

An earlier preprint describes the first DIMBA design, which used latent diffusion. That design has been replaced and the preprint is kept only for the record.
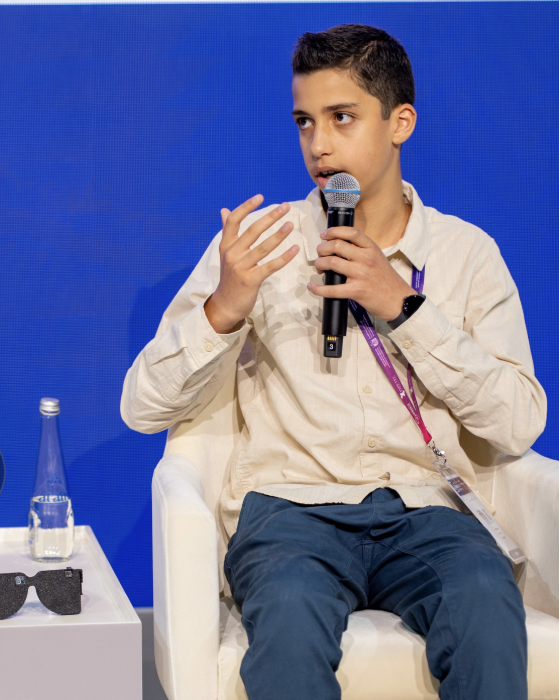
Founded by Faris Allafi.

An independent lab in Abu Dhabi, led by Faris Allafi, architect of DIMBA and one of the youngest published researchers working on post-transformer architectures.

The current generation of language models is defined by an architectural choice, not a law of nature. Better dynamics are worth building openly, with technical depth as the currency.

Formerly operating as DimbaLabs.

Faris Allafi speaking on a panel

Build what comes next.

faris@hamiltonianresearch.xyz